See Where Your AI Tokens Are Going
When we asked research teams about their biggest concerns around AI costs, two issues stood out. One was burning through a token allotment faster than expected; the other was not being able to see what was driving the spend in the first place. Those two issues are clearly connected. It's hard to control a bill you can't break down, and most teams get a monthly total with little detail about where the money went.
Luckily, we can provide some reassurance on that front. Token costs are more legible than they look, once you know what you're paying for and where the waste tends to collect.
What You're Paying For
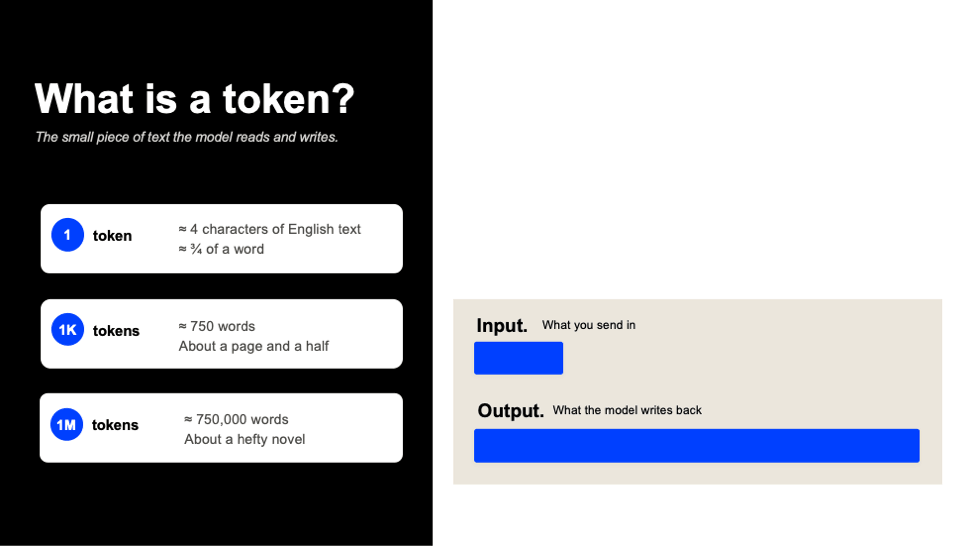
A token is the small unit of text a model reads and writes, roughly four characters or three-quarters of a word. A thousand tokens run to about 750 words or about a page and a half. A million tokens, the context window on a model like Claude Opus 4.8, come to around 750,000 words (basically a hefty novel).
Two factors explain most of a research bill:
First, output costs far more than input, on the order of five times per token. This means that using clear, specific prompts to constrain what comes back is one of the easiest ways to save money. Left unguided, most models write far more than the task needs.
Second, not all text costs the same to process. Plain text is cheap, but DOIs, URLs, and raw HTML are expensive because odd character strings get broken into many small tokens. So, a workflow heavy on links and web pages costs more than you might expect from the word count alone.
Where The Tokens Go In A Literature Workflow
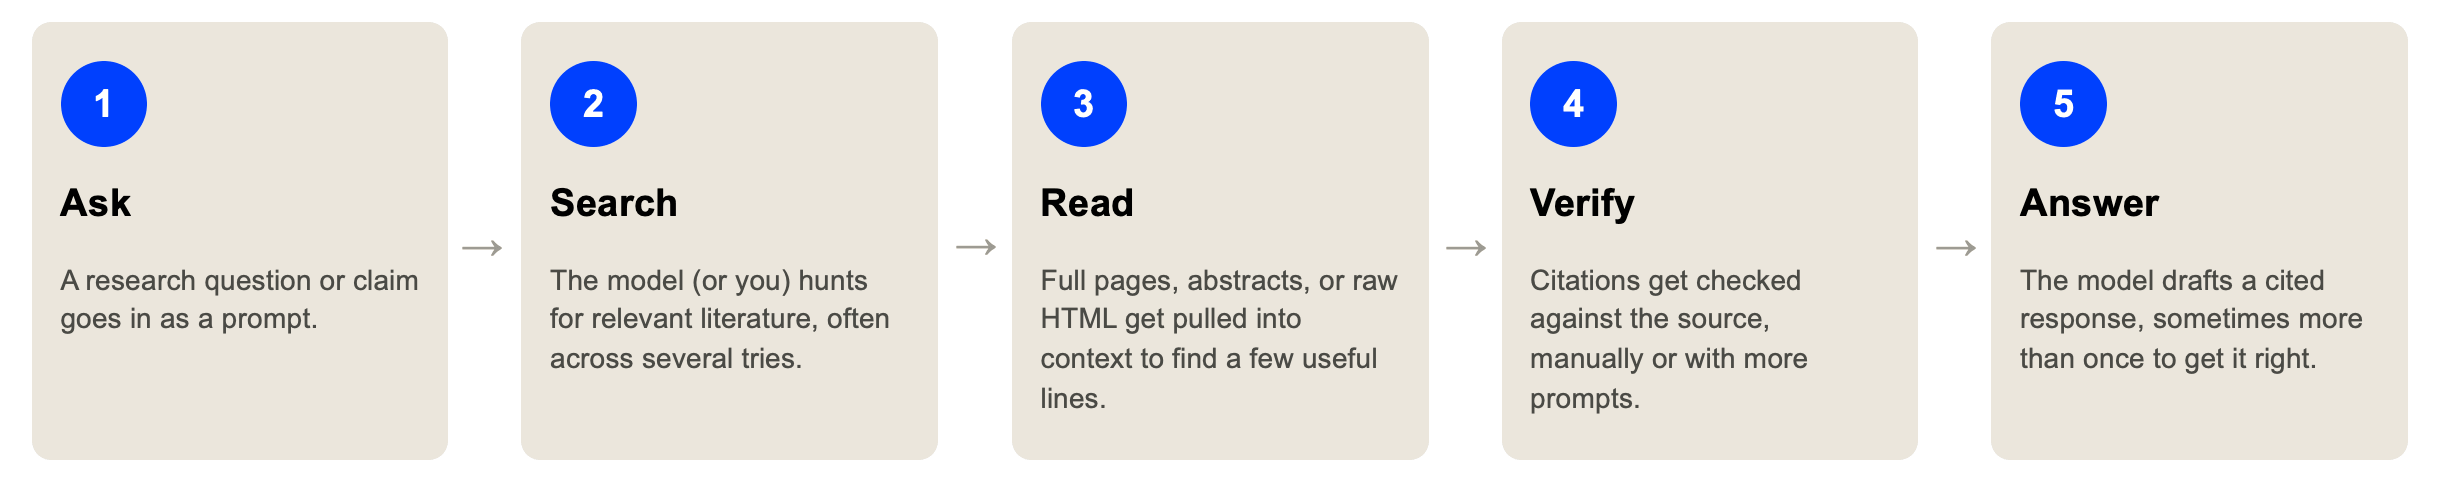
If you follow a typical literature task, you can watch token use add up at each step. You ask a question, and the model searches for relevant papers, often trying several times. It reads full pages, abstracts, and HTML to find a few useful lines of information. It checks citations, sometimes needing extra prompts. Then it drafts a cited answer, frequently more than once before it gets it right. Each step adds tokens, and most use more than what's needed for the final answer.
Some habits can quietly increase your costs:
Sending the most expensive model to do routine lookup work.
Re-searching claims a tool already checked.
Pasting raw pages instead of structured evidence.
Re-prompting after a fabricated citation rather than grounding the first pass.
And the token meter is only part of the real expense.
When a model answers a literature question from memory, even the best ones will occasionally invent a citation, and smaller models do it more often. A fabricated DOI caught late, a round of re-prompting to coax out an accurate source, a colleague re-checking references by hand: that downstream rework often costs more time than the tokens cost in dollars.
The Anatomy Of A Literature Workflow
Grounding Beats A Bigger Model
Most teams reach for the largest model by default, on the assumption that a bigger model means more reliable research. But for finding and verifying literature, that's not always true. The most advanced models are worth the cost when they need to search and reason their way across the open web and judge what's relevant and trustworthy. Give the model verified evidence up front and the hard work is already done. That's what Scite does. It gives the model verified papers and citation context before any reasoning starts, so the model only needs to read the evidence and cite it. A smaller model can do this just as well as a large one.
The cost difference is significant. In Scite's internal tests, with the same grounding applied across a range of Claude models, a single answer that cost 100 on Claude Opus cost about 85 on Claude Sonnet and about 30 on Claude Haiku. That's roughly three times cheaper on the smallest tier. Citation accuracy held across all three, because it comes from the sources, not the model.
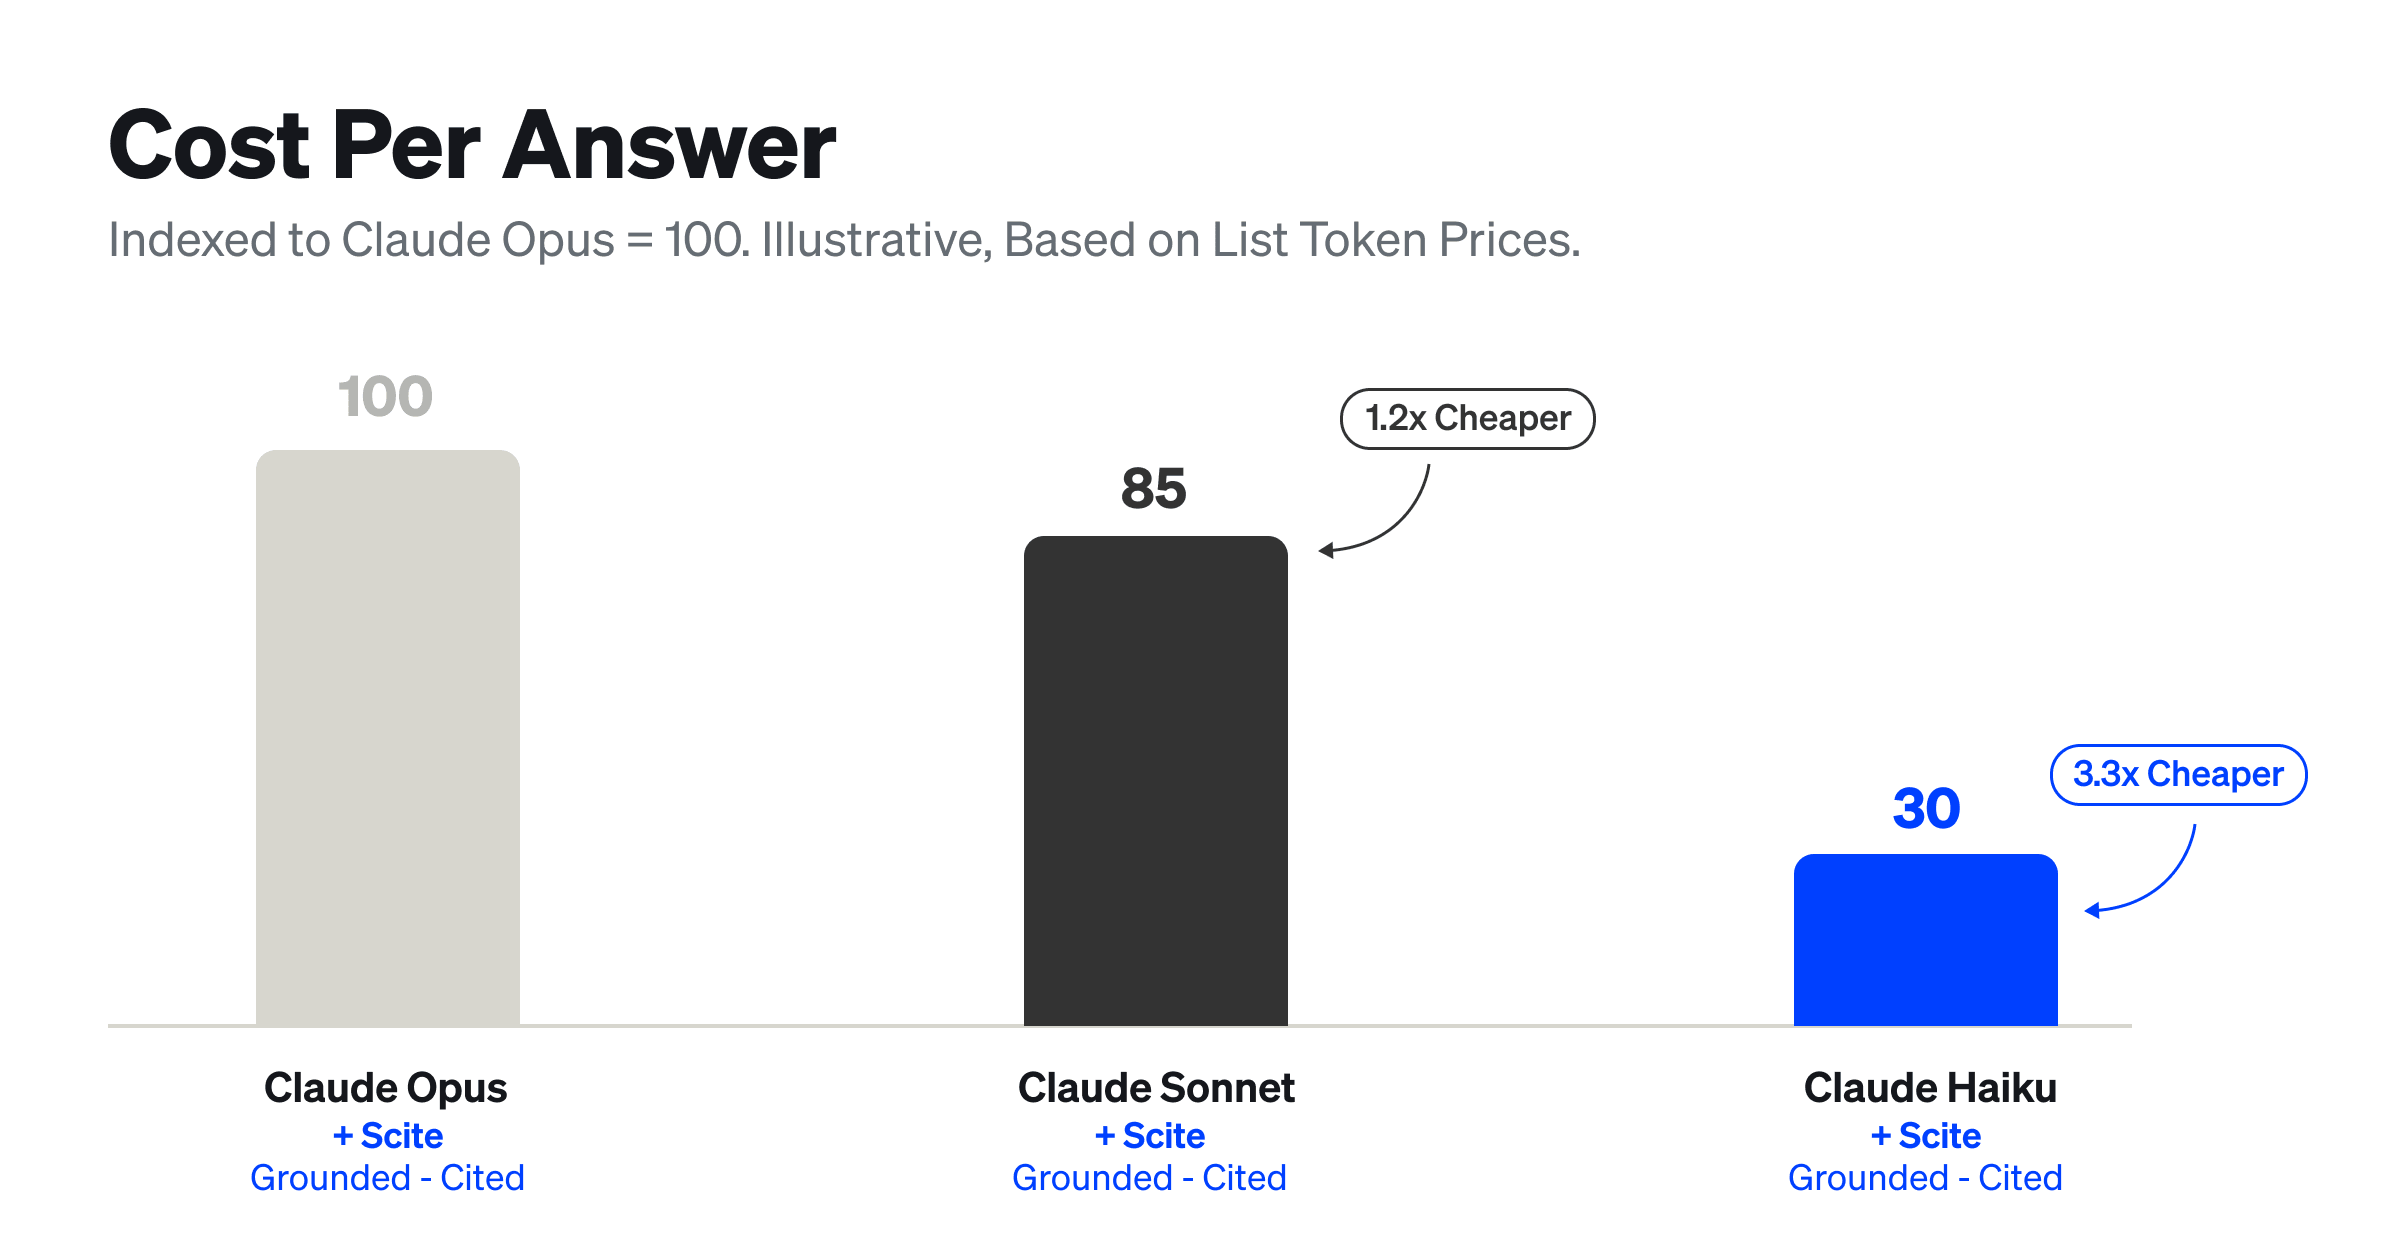
These figures are illustrative and directionally consistent with the test runs. They are intended to show the shape of the savings and should not be interpreted as a fixed quote.
Grounding also changes how much effort sourcing takes.
To verify one specific claim or reference, a grounded call does the work in a single round-trip: the model sends one request to Scite and reads back a structured set of evidence. That evidence arrives already sorted, with supporting and contrasting signals and retraction flags attached. It usually amounts to about 15,000 tokens and is pulled from Scite's database of over 280 million papers and 1.6 billion Smart Citations.
In contrast, if a model tries to check the same claim by browsing the open web, it plays out a bit differently. It usually ends up making three or four round-trips, sending request after request and reading each page back, reaching maybe one in three sources since the rest sit behind paywalls or blocks. It also pulls in raw HTML, which can run up to more than 200,000 tokens.
A fair caveat: that single-call comparison is for a targeted claim. An open-ended literature review leads to many round-trips regardless of whether or not it is grounded. How you write the prompt shapes that significantly. A more specific question, one that names a paper, a claim, or a defined scope, keeps the call count lower and the token cost closer to that single-trip baseline.
More Ways To Bring The Bill Down
Grounding is one way to save. There are a few other strategies, many drawn from how engineering teams already manage AI spend.
Smart model routing sends each request to the cheapest model that can handle it, rather than defaulting to the largest for everything. Tools like OpenRouter, LiteLLM, and Portkey sit in front of an API for this, and it's often the highest-impact change available.
Prompt caching, a native feature of the Claude API, stops you from paying to rebuild the same context on each request. Repeated inputs (a long system prompt or a set of tool schemas) are stored in a cache, so they aren't billed again and again.
Persistent memory layers, such as Mem0 and Zep, retrieve only the facts a request needs instead of resending the full conversation history each turn.
Batch processing via Anthropic's Batch API discounts asynchronous work like bulk literature reviews.
These savings are based on third-party reports, not our own benchmarks, and real savings depend on your workload, but the trend is consistent.
If you're not using an API, there are still small steps you can take. Set a sensible default model for your team versus letting everyone use the most expensive one. Start a new chat for each task, because long threads rebuild all their context every time and get more expensive as they grow.
Seeing Where It Goes
All of this is easier to manage once you can measure it. Some environments show per-query cost directly. Claude Code, for instance, displays the model, the running context, and the dollar amount as you work. You can even have it write a short cost report after each run, itemizing the tokens used for input, output, and cache. Scite has published a prompt-cost skill which does precisely that, offering a self-contained report of the tokens and dollars a prompt consumed. Not every tool exposes this, though. For web and desktop apps without per-query detail, admin analytics give a usage-level view.
It helps to tie spend to output. A number on its own invites anxiety; the same number set against what it produced (a completed literature review, a verified reference list, a drafted section) is easier to understand, justify, and monitor. When you can look at a prompt and ask whether the result was worth the cost, you can begin to adjust and tune the prompts and models you use most.
Grounding is the piece pulling double duty. It lowers the token bill and increases trust in the results. Connect Scite to the AI tool your team already uses, and your next literature query will come back cited, verified, and cheaper to run.
Connect Scite → https://scite.ai/mcp
Run the prompt-cost skill in your own setup → https://bit.ly/4c6yeg6